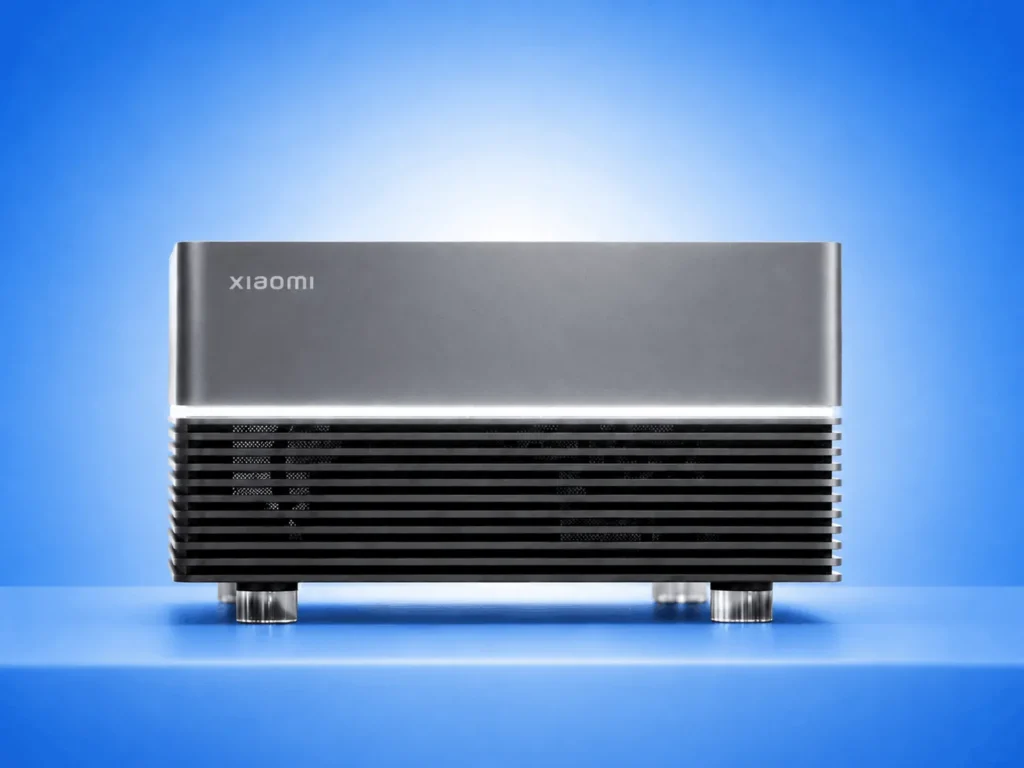
We get it. You saw Xiaomi’s AI Cube, a little box with 80 GB of memory built to run big language models at home, and you went straight to the obvious question: how much, and where do I click “buy”? We asked the same thing, with the same slightly too-fast heartbeat. The answer is short and a bit of a let-down: there is no price and there is no button. So we did the useful thing instead. We took the Cube and the 4 machines with 64 to 192 GB of unified memory that already have a manufacturer price, and ran all five through the same arithmetic we use for every machine on this site, against the same 26 models.
 Xiaomi AI Cube, 80 GB — engineering prototypePrototype · Hardware sheet
The good news is that the thing the Cube promises — one small box that holds a model too big for a gaming graphics card — is already priced, in 4 flavours, from $2,899 to $6,799. Which one is worth it depends on the models you want to run, how much text you feed them and how long you are willing to wait for the answer. Let’s go through them.
The five machines side by side
The number that decides whether a model runs is not the memory on the box: it is the memory left for the model once the system has taken its share. On Apple machines that is the total minus the 3 GiB we reserve for the operating system. On AMD Ryzen AI Max machines there is a second limit, and it is easy to miss: AMD caps how much of that memory the graphics side can use.
| Machine | Memory | Left for the model | Memory bandwidth | Manufacturer price (US) | Models that fit at 32k | Context ceiling for gpt-oss-120b |
|---|---|---|---|---|---|---|
| Mac mini, M5 Pro, 64 GB | 64 GB | 61.00 GiB | 307 GB/s (Apple) | $2,899 | 20 of 26 | 32k tokens |
| Xiaomi AI Cube, 80 GB | 80 GB | 77.00 GiB | 341 GB/s (our estimate) | none: prototype | 22 of 26 | 128k tokens |
| PC, Ryzen AI Max+ 395, 128 GB | 128 GB | 96.00 GiB | 256 GB/s (derived) | $3,449 | 23 of 26 | 128k tokens |
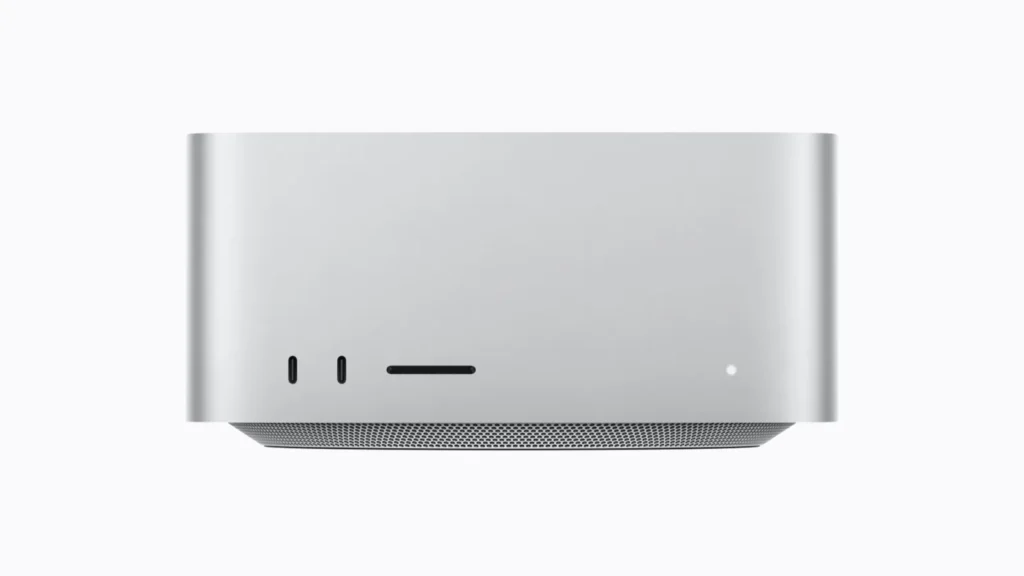
| Mac Studio, M5 Max, 128 GB | 128 GB | 125.00 GiB | 614 GB/s (Apple) | $5,099 | 23 of 26 | 128k tokens |
| PC, Ryzen AI Max+ PRO 495, 192 GB | 192 GB | 160.00 GiB | 273 GB/s (derived) | $6,799 | 24 of 26 | 128k tokens |
Models are counted at the reference compression (Q4_K_M, or the nearest one the author publishes), and 128k is the most gpt-oss-120b itself accepts, so on 4 of the 5 machines the limit is the model, not the box. Three things jump out, and the rest of this piece is about them. The 64 GB Mac already holds gpt-oss-120b. The two 128 GB machines take exactly the same models despite a 29 GiB gap. And the Cube, the one you cannot buy, lands in the middle of the table, not at the top.
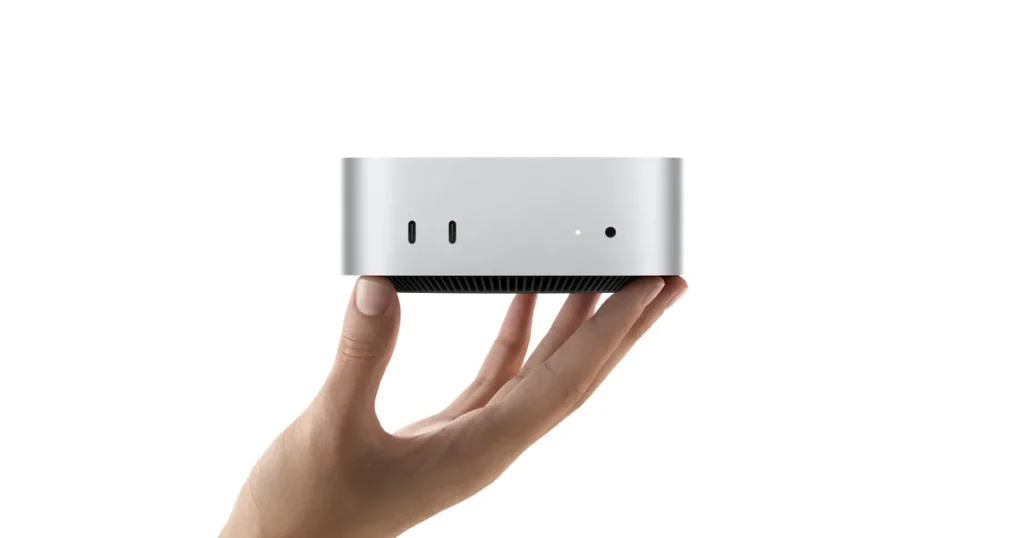
Mac mini with M5 Pro, 64 GB: the cheapest ticket to a 120B
 Mac mini with M5 Pro and 64 GBHardware sheet
This is the smallest machine on sale in this comparison that runs gpt-oss-120b, and that alone makes it interesting. Apple charges $2,899 in its US store for the configuration with 64 GB and 512 GB of storage (price read on 1 October 2026). That is $1,200 above the $1,699 the M5 Pro Mac mini starts at, because the starting model has 24 GB, and 24 GB will not get you anywhere near this list.
With 61.00 GiB left for the model, it takes 20 of our 26 models at 32k of context. The 6 it leaves out are the 6 heaviest files in the catalogue: llama4-scout-17b (60.87 GiB of weights alone, so it misses by a whisker once the cache and the runtime’s working memory are added), nemotron-3.5-super-120b (65.29 GiB: here the weights alone are already too much), qwen3.8-flash-next, deepseek-v4-flash, glm-5.3-flash and glm-5.2.
The catch is the ceiling. gpt-oss-120b is a 58.46 GiB file, and in 61.00 GiB it fits at 32k of context and not one step further. Think of it as a suitcase you can close if you sit on it: it closes, but there is no room for the souvenirs. For chatting and for most documents, 32k is plenty. For feeding it a whole codebase, it is not.
Ryzen AI Max+ 395, 128 GB: why 128 is really 96
 PC with Ryzen AI Max+ 395 and 128 GB unifiedHardware sheet
Here is the number that surprised us most. A PC with AMD’s Ryzen AI Max+ 395 and 128 GB of unified memory does not give the model 125 GiB, as a Mac with the same memory would. AMD itself says that this generation “topped out at 128GB of total memory with up to 96GB reserved for GPU workloads”, so our engine counts 96.00 GiB. That is the figure every verdict on its sheet is worked out from.
And still, 96 GiB is a lot. It takes 23 of the 26 models at 32k and 21 at 128k. It holds gpt-oss-120b at 128k, its full declared maximum, llama4-scout-17b up to 256k, the 87.25 GiB qwen3.8-flash-next up to 128k, and nemotron-3.5-super-120b at its own declared maximum. The 3 it cannot take are deepseek-v4-flash (127.28 GiB), glm-5.3-flash (187.04 GiB) and glm-5.2 (433.83 GiB).
On price, Framework lists its Desktop with the Max+ 395 and 128 GB at $3,449 before tax, and the page marked that configuration as out of stock when we checked it on 30 September 2026. In May 2026, AMD gave $3,999 as the retail price of its own 395 machine with 128 GB, the Ryzen AI Halo. Either way, it is the cheapest route in this comparison to the 87 GiB model.
Opens on YouTube (no cookies) only when you press play. More videos on its sheet →
Mac Studio with M5 Max, 128 GB: the same list, twice the speed
 Mac Studio with M5 Max and 128 GBHardware sheet
Same 128 GB on the box, and this time 125.00 GiB for the model, because Apple publishes no separate GPU cap; macOS keeps a default limit that one setting raises (iogpu.wired_limit_mb), and our figure assumes you raise it. You would expect those extra 29 GiB to buy you more models. They do not.
Where the Mac Studio pulls away is speed. Apple declares 614 GB/s of memory bandwidth for this chip, against 256 GB/s on the 395, and when a model writes its answer it has to read the weights it uses again for every token. Our engine’s estimate for gpt-oss-120b is about 36 tokens per second on the Mac Studio and about 14 on the 395. For qwen3.6-35b-a3b, about 102 against about 39. These speeds are estimates from a public formula, not measurements, and they never decide whether a model fits; but a 2.4-fold gap in bandwidth is not something an estimate makes up.
The bill: $5,099 in Apple’s US store for the M5 Max with 128 GB and 512 GB of storage (read on 1 October 2026). That is $1,650 more than the Framework listing for the same model list. What you are paying for is answers that arrive more than twice as fast, by our estimate, and qwen3.8-flash-next and llama4-scout-17b stretching twice as far.
Ryzen AI Max+ PRO 495, 192 GB: the only one that loads deepseek-v4-flash
 PC with Ryzen AI Max+ PRO 495 and 192 GB unifiedHardware sheet
This is the last of the five to reach buyers, and the biggest. AMD’s Ryzen AI Max+ PRO 495 takes up to 192 GB, of which, in AMD’s words, “up to 160GB dedicated to the GPU”. Our engine counts 160.00 GiB for the model: 29 fewer than a 192 GB Mac would leave, and still 35 more than the Mac Studio above.
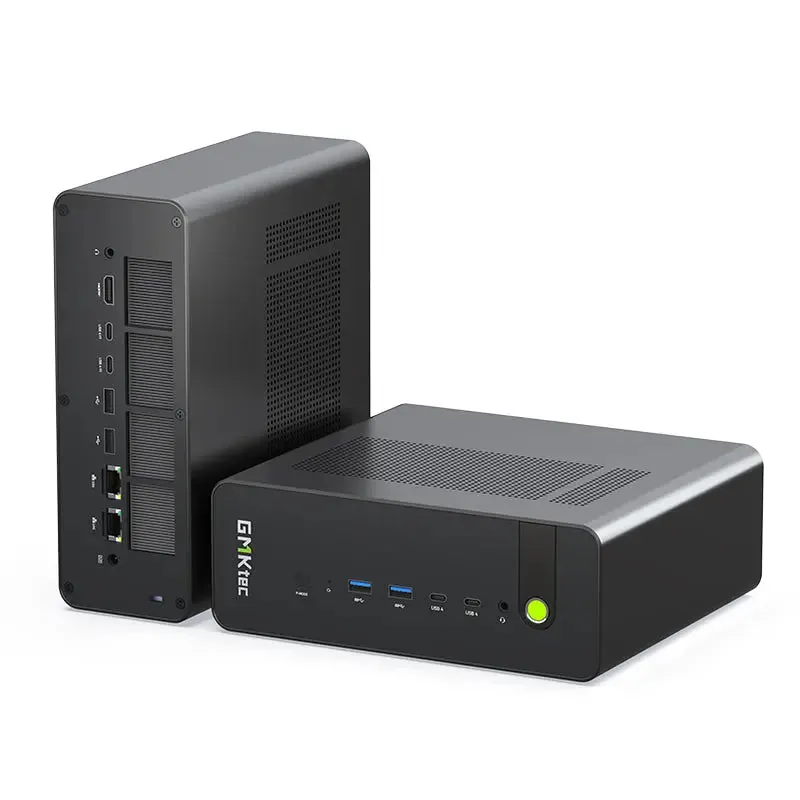
Those 160 GiB are what lets it do the one thing no other machine in this comparison does: hold deepseek-v4-flash, a 127.28 GiB file at its reference compression, up to 256k of context. It takes 24 of the 26 models at 32k and 22 at 128k. The 2 left out are glm-5.3-flash, whose 187.04 GiB overflow even these 160, and glm-5.2, which at 433.83 GiB is not a home-machine model by anyone’s arithmetic.
GMKtec sells its EVO-X5 Pro with this chip, 192 GB and 2 TB of storage at $6,799 in its own store (it was $6,599 until early October; checked again on 9 October 2026), and on 30 September it was already shipping. That makes it the most expensive box here, and the only one you would buy for a single reason: a model that does not fit in the Mac Studio’s 125 GiB but does fit in 160, which in our catalogue today means deepseek-v4-flash.
Opens on YouTube (no cookies) only when you press play. More videos on its sheet →
And the AI Cube? Right in the middle
Now put the Cube back on the table. With 80 GB and 77.00 GiB for the model, it takes 22 of the 26 models at 32k: 2 more than the 64 GB Mac mini, and 1 or 2 fewer than everything else here. Compared with the Mac mini, what it adds is llama4-scout-17b (up to 128k), nemotron-3.5-super-120b (up to 256k, and at 65.29 GiB the biggest file the Cube holds) and a far roomier gpt-oss-120b, which goes from 32k to 128k. Compared with the 395 PC and the Mac Studio, it is simply behind: no qwen3.8-flash-next, a shorter reach for llama4-scout-17b (128k against 256k and 512k) and the same 128k ceiling for gpt-oss-120b.
One honest caveat. The Cube’s speed is the one figure on this page we cannot pin down at all: Xiaomi has not published the bandwidth of its 80 GB, so the 341 GB/s on its sheet is our own estimate, labelled as such. The 1.22 TB/s attached to the Cube belongs to the memory stacked on one of its chips, not to the 80 GB where a model actually sits; we unpacked that in our Mac mini M6 vs AI Cube comparison. Memory, on the other hand, decides the fit, and 80 GB is the figure every verdict above starts from.
What we could not verify
- AMD publishes no bandwidth in GB/s. The 256 and 273 GB/s come from the memory type and speed AMD does publish (a 256-bit bus at 8,000 and 8,533 MT/s). That is arithmetic, not a measurement, and the sheets say so.
- The AMD GPU ceilings are AMD’s published figures. On Linux the limit can be adjusted, and AMD does not publish a maximum for that; we use the 96 and 160 GB it does state, so a tuned machine could give more, by an amount AMD does not state.
- On a Mac, the memory for the model assumes one setting. macOS keeps a default limit on how much memory the GPU may lock, and
iogpu.wired_limit_mbraises it; the 61.00 and 125.00 GiB above assume you raise it, which matters most forgpt-oss-120bon the 64 GB Mac mini. - Every speed on this page is an estimate. Fit is calculated from the real file sizes and the cache each model’s architecture needs; tokens per second come from a bandwidth formula, and on the Cube from a bandwidth that is itself an assumption.
- Prices are US prices published by each manufacturer, in dollars, on the dates given. None of the AMD machines publishes a euro price.
So which one should you buy?
If none of the big 6 models is on your list, all 5 machines take the same 20 at 32k, from qwen3-1.7b to gpt-oss-120b. Then the choice is about speed, price and whether you prefer macOS or a PC. Plenty to have fun with either way.
Which of the 26 models fits on your machine, at the context your work needs and in the language you work in, is what the Model Finder answers, and the full list of 18 machines carries every figure with its evidence label. Once the box is on your desk, our llama.cpp setup guide starts a model with 1 command, and on a Mac the MLX guide is the other road worth knowing.