Hardware
Choosing a machine to run AI at home is the fun part, right up until you reach the small print. Every hardware sheet answers the question the spec sheet dodges: how much memory is really left once the system takes its share (it always helps itself first), and which of the models we measure fit in what remains — with the context each one can actually hold. Two lists per machine, the ones that fit and the ones that do not, so you can see what not to buy.
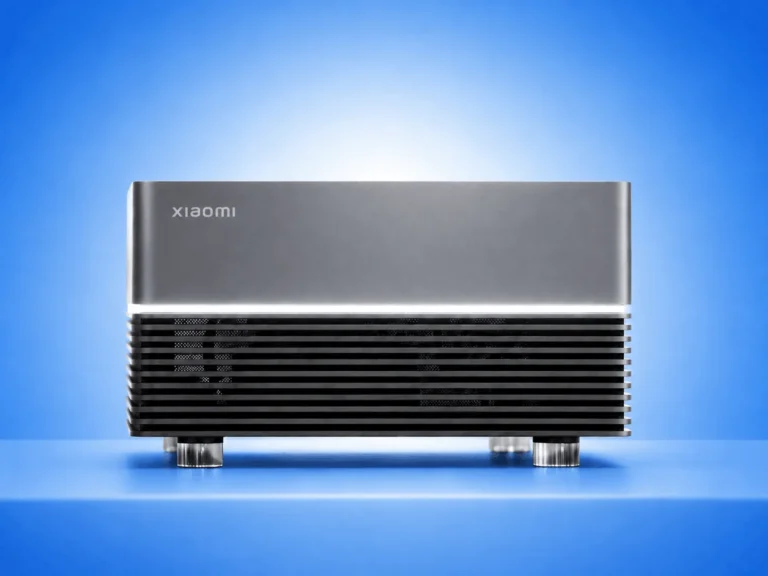 Prototype5Xiaomi AI Cube, 80 GB — engineering prototype80 GB
 4Mac mini with M6 and 32 GB32 GB
 3Mac Studio with M5 Max and 128 GB128 GB3Mac mini with M5 Pro and 64 GB64 GB4Mac Studio with M5 Ultra and 512 GB512 GB3Mac mini with M6 and 16 GB16 GB
 3Mac with M4 Max and 64 GB64 GB
 2Mac with M4 Pro and 24 GB24 GB
 2Mac with M4 and 16 GB unified memory16 GB
 2Workstation with an RTX 4090 24 GB24 GB
 3PC with an RTX 3060 12 GB12 GB
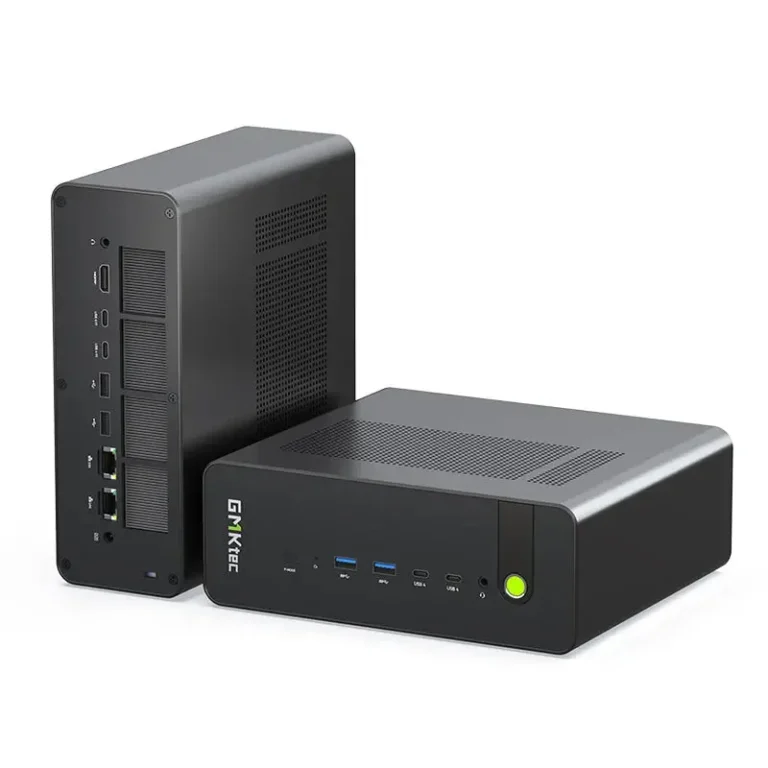 2PC with Ryzen AI Max+ PRO 495 and 192 GB unified192 GB
 2PC with Ryzen AI Max+ 395 and 128 GB unified128 GB2PC with an RTX 4060 8 GB8 GBPC with an RTX 4070 12 GB12 GB3Server with 2× RTX 3090 (48 GB)48 GBClass of machineMini-PC with an NPU and 32 GB LPDDR5X32 GBClass of machineOffice laptop, CPU only, 16 GB16 GB
| Machine | Memory left for the model | Bandwidth | Models that fit at 8k | and at 32k | Largest model it takes |
|---|---|---|---|---|---|
| PC with an RTX 4060 8 GB | 7.20 GiB | 272 GB/s derived, not published | 7 / 26 | 3 / 26 | qwen3.5-9b 5.29 GiB |
| PC with an RTX 3060 12 GB | 11.20 GiB | 360 GB/s derived, not published | 8 / 26 | 8 / 26 | gemma4-12b 6.63 GiB |
| PC with an RTX 4070 12 GB | 11.20 GiB | 504 GB/s derived, not published | 8 / 26 | 8 / 26 | gemma4-12b 6.63 GiB |
| Mac mini with M6 and 16 GB | 13.00 GiB | 153 GB/s vendor declared | 9 / 26 | 9 / 26 | gpt-oss-20b 10.83 GiB |
| Mac with M4 and 16 GB unified memory | 13.00 GiB | 120 GB/s vendor declared | 9 / 26 | 9 / 26 | gpt-oss-20b 10.83 GiB |
| Office laptop, CPU only, 16 GB | 13.00 GiB | 83 GB/s estimated | 9 / 26 | 9 / 26 | gpt-oss-20b 10.83 GiB |
| Mac with M4 Pro and 24 GB | 21.00 GiB | 273 GB/s vendor declared | 16 / 26 | 14 / 26 | qwen3-coder-30b 17.28 GiB |
| Workstation with an RTX 4090 24 GB | 23.20 GiB | 1008 GB/s vendor declared | 17 / 26 | 17 / 26 | qwen3.6-35b-a3b 20.61 GiB |
| Mac mini with M6 and 32 GB | 29.00 GiB | 170 GB/s vendor declared | 19 / 26 | 19 / 26 | nemotron-3.5-lightning-30b 23.73 GiB |
| Mini-PC with an NPU and 32 GB LPDDR5X | 29.00 GiB | 120 GB/s estimated | 19 / 26 | 19 / 26 | nemotron-3.5-lightning-30b 23.73 GiB |
| Server with 2× RTX 3090 (48 GB) | 47.20 GiB | 936 GB/s vendor declared | 19 / 26 | 19 / 26 | nemotron-3.5-lightning-30b 23.73 GiB |
| Mac mini with M5 Pro and 64 GB | 61.00 GiB | 307 GB/s vendor declared | 20 / 26 | 20 / 26 | gpt-oss-120b 58.46 GiB |
| Mac with M4 Max and 64 GB | 61.00 GiB | 546 GB/s vendor declared | 20 / 26 | 20 / 26 | gpt-oss-120b 58.46 GiB |
| Xiaomi AI Cube, 80 GB — engineering prototype | 77.00 GiB | 341 GB/s estimated | 22 / 26 | 22 / 26 | nemotron-3.5-super-120b 65.29 GiB |
| PC with Ryzen AI Max+ 395 and 128 GB unified | 96.00 GiB | 256 GB/s derived, not published | 23 / 26 | 23 / 26 | qwen3.8-flash-next 87.25 GiB |
| Mac Studio with M5 Max and 128 GB | 125.00 GiB | 614 GB/s vendor declared | 23 / 26 | 23 / 26 | qwen3.8-flash-next 87.25 GiB |
| PC with Ryzen AI Max+ PRO 495 and 192 GB unified | 160.00 GiB | 273 GB/s derived, not published | 24 / 26 | 24 / 26 | deepseek-v4-flash 127.28 GiB |
| Mac Studio with M5 Ultra and 512 GB | 509.00 GiB | 1200 GB/s vendor declared | 26 / 26 | 26 / 26 | glm-5.2 433.83 GiB |
Fitting means the model file, its context memory and the runtime headroom all fit in what is left after the system takes its share, at Q4_K_M or the nearest compression the author publishes. Bandwidth carries its provenance in the cell: 8 of these 18 figures are not published by the manufacturer anywhere, and we say so rather than passing them off as specifications.
The Xiaomi AI Cube is a prototype, and in the table its bandwidth reads estimated, not vendor declared. This video explains why a bandwidth figure only counts when it belongs to the memory the model actually sits in. In our table, every bandwidth cell says where its figure comes from.
Opens on YouTube (no cookies) only when you press play. More videos on its sheet →