Home›Hardware›PC with Ryzen AI Max+ PRO 495 and 192 GB unified
PC with Ryzen AI Max+ PRO 495 and 192 GB unified
AMD chip with unified memory192 GiB273 GB/s15.4 TFLOPS
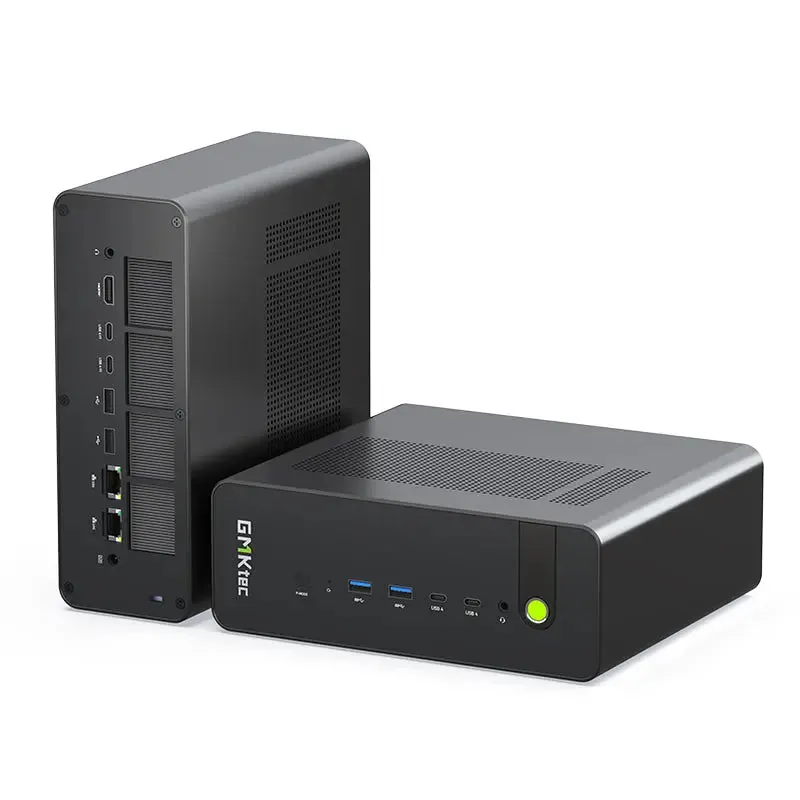
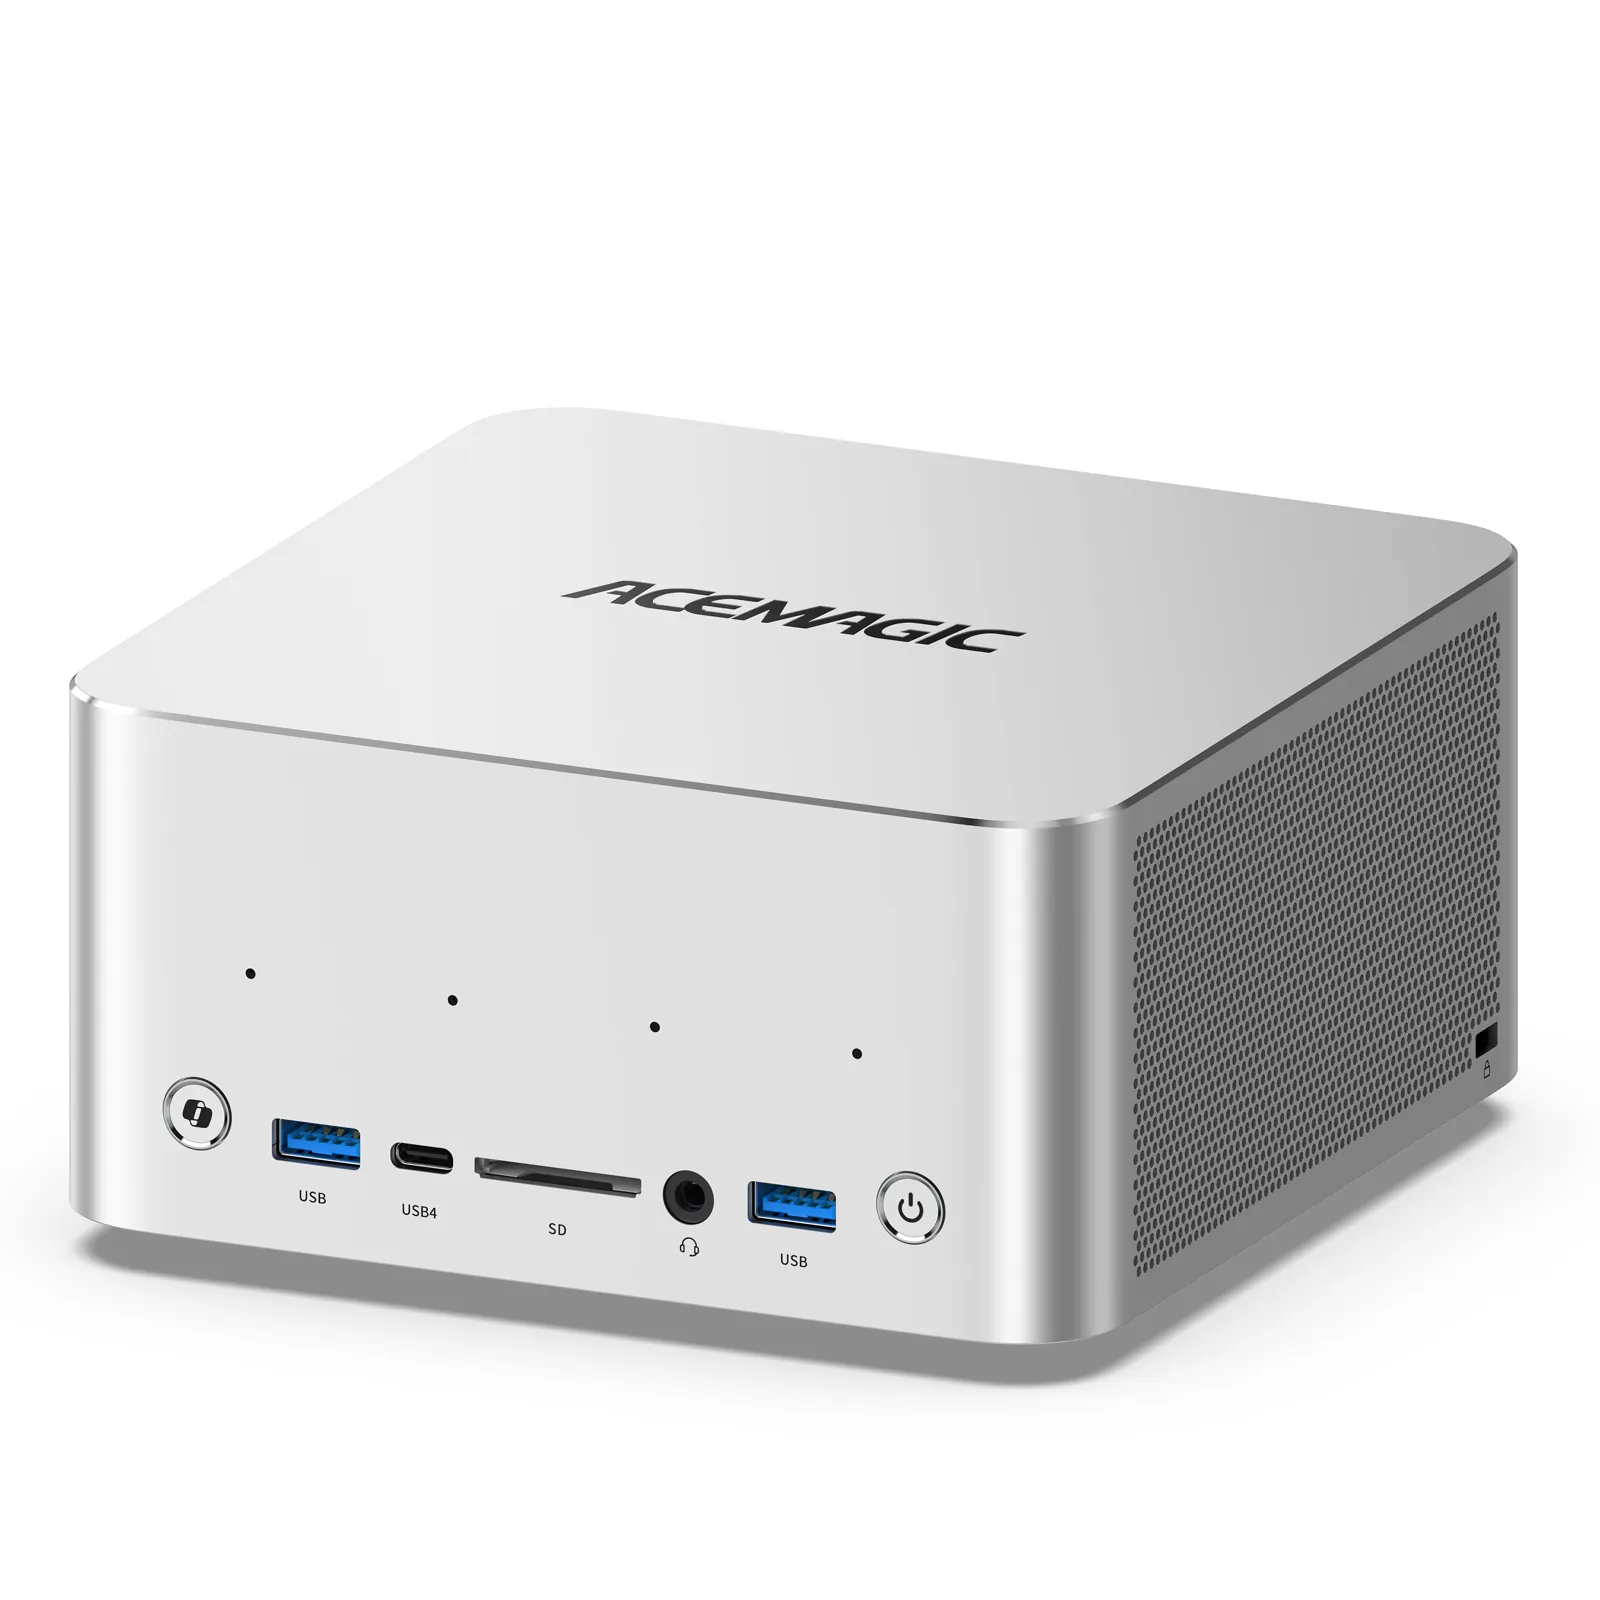
This machine leaves 160.00 GiB for the model once the system has its share, and it takes 19 of the 20 models we measure at the reference compression. What decides how fast it answers is not the chip: it is the 273 GB/s of memory bandwidth.
Left for the model
Estimated
Memory bandwidth
Estimated
Models that fit
Measured by Local AI Scope
Videos: PC with Ryzen AI Max+ PRO 495 and 192 GB unified 2
Official footage and the best walk-throughs we found. Press play and it opens right here.
The videos live on YouTube, and nothing loads from there until you press play (no-cookie mode). The thumbnail is served by us.
The memory you can actually use
Unified memory is shared with the operating system and everything you have open. The reserve here is deliberately conservative; you can change it in the tool.
| Memory | GiB |
|---|---|
| Memory on the box | 192 |
| Reserved for the system | −3.00 |
| Beyond the limit the manufacturer sets for the GPU | −29.00 |
| Left for the model | 160.00 |
192 GB on the box, 160 for the model. AMD states that the Ryzen AI Max+ PRO 495 can dedicate up to 160 GB of its 192 GB to the graphics processor, and the graphics processor is what runs the model. So every figure on this page is computed with 160, not with the 189 that the box minus our system reserve would give. On Linux that limit is a driver setting that AMD documents as adjustable, but it publishes no maximum figure for it: we stick to the figure it does publish.
Memory bandwidth
Two different limits, and people confuse them constantly. While the model is writing its answer, bandwidth rules: every single token means reading the weights again, so tokens per second is roughly bandwidth divided by model size. While the model is reading your document, compute rules: the whole input is processed at once. That is why a laptop with no GPU can take minutes before the first word appears and then type at a tolerable pace.
273 GB/s — Derived, not published by the manufacturer · the manufacturer publishes the bus width but neither the memory speed nor the bandwidth. This figure is the usual arithmetic derivation () and we could not confirm it at source (Source).
Compute: 15.4 TFLOPS (estimate for this class of machine) — Estimated · the manufacturer does not publish this figure at all; ours is a conservative estimate, not a specification. The figures in this line do not all come from the same measure across machines, because each manufacturer publishes a different one. Compare them between machines only with that in mind.
Which models fit here, and which do not
Fitting means three things at once fit in the memory left over: the model file, its context memory, and the runtime’s working headroom. Context memory is computed from each model’s declared attention pattern layer by layer, not from the generic formula — which is why several models fit here that other calculators say do not.
| Model | Compression shown | Model size | 8k | 32k | 128k | Largest context that fits |
|---|---|---|---|---|---|---|
| qwen3-1.7b | Q4_K_M |
1.03 GiB | yes | yes | — | 32k |
| qwen3-4b-2507 | Q4_K_M |
2.33 GiB | yes | yes | yes | 256k |
| gemma4-e2b | Q4_K_M |
2.89 GiB | yes | yes | yes | 128k |
| gemma4-e4b | Q4_K_M |
4.63 GiB | yes | yes | yes | 128k |
| qwen3-8b | Q4_K_M |
4.68 GiB | yes | yes | — | 32k |
| granite-4.2-8b | Q4_K_M |
4.98 GiB | yes | yes | yes | 128k |
| gemma4-12b | Q4_K_M |
6.63 GiB | yes | yes | yes | 256k |
| gpt-oss-20b | Q4_K_M |
10.83 GiB | yes | yes | yes | 128k |
| mistral-small-24b | Q4_K_M |
13.35 GiB | yes | yes | yes | 128k |
| qwen3.8-27b | Q4_K_M |
15.33 GiB | yes | yes | yes | 256k |
| qwen3.6-27b | Q4_K_M |
15.66 GiB | yes | yes | yes | 256k |
| gemma4-26b-a4b | Q4_K_M |
15.78 GiB | yes | yes | yes | 256k |
| gemma4-31b | Q4_K_M |
17.07 GiB | yes | yes | yes | 256k |
| qwen3-coder-30b | Q4_K_M |
17.28 GiB | yes | yes | yes | 256k |
| qwen3.6-35b-a3b | Q4_K_M |
20.61 GiB | yes | yes | yes | 256k |
| gpt-oss-120b | Q4_K_M |
58.46 GiB | yes | yes | yes | 128k |
| llama4-scout-17b | Q4_K_M |
60.87 GiB | yes | yes | yes | 256k |
| qwen3.8-flash-next | IQ4_XS |
87.25 GiB | yes | yes | yes | 256k |
| deepseek-v4-flash | IQ4_XS |
127.28 GiB | yes | yes | yes | 256k |
| glm-5.2 | Q4_K_M |
433.83 GiB | no | no | no | — |
Sizes are the real published files at the reference compression, one step per row: Q4_K_M where the author publishes it, the nearest neighbour where they do not. Every row states which one it is showing. Q4_K_M is our quality floor: below it the loss is audible in the answers. A model that would only fit here at a harsher compression is listed as not fitting, on purpose. A dash in a context column means the model itself does not offer that context, so there is nothing to fit.
Models that fit — 19 of the 20 models measured
- qwen3-1.7b
Q4_K_M— context 32k tokens - qwen3-4b-2507
Q4_K_M— context 256k tokens - gemma4-e2b
Q4_K_M— context 128k tokens - gemma4-e4b
Q4_K_M— context 128k tokens - qwen3-8b
Q4_K_M— context 32k tokens - granite-4.2-8b
Q4_K_M— context 128k tokens - gemma4-12b
Q4_K_M— context 256k tokens - gpt-oss-20b
Q4_K_M— context 128k tokens - mistral-small-24b
Q4_K_M— context 128k tokens - qwen3.8-27b
Q4_K_M— context 256k tokens - qwen3.6-27b
Q4_K_M— context 256k tokens - gemma4-26b-a4b
Q4_K_M— context 256k tokens - gemma4-31b
Q4_K_M— context 256k tokens - qwen3-coder-30b
Q4_K_M— context 256k tokens - qwen3.6-35b-a3b
Q4_K_M— context 256k tokens - gpt-oss-120b
Q4_K_M— context 128k tokens - llama4-scout-17b
Q4_K_M— context 256k tokens - qwen3.8-flash-next
IQ4_XS— context 256k tokens - deepseek-v4-flash
IQ4_XS— context 256k tokens
Models that do not fit — 1 of the 20 models measured
- glm-5.2
Q4_K_M— short by 289.13 GiB
The machines on either side
- Xiaomi AI Cube, 80 GB — engineering prototype — 77.00 GiB left for the model, 17 / 20 models
- PC with Ryzen AI Max+ 395 and 128 GB unified — 96.00 GiB left for the model, 18 / 20 models
- Mac Studio with M5 Max and 128 GB — 125.00 GiB left for the model, 18 / 20 models
- Mac Studio with M5 Ultra and 512 GB — 509.00 GiB left for the model, 20 / 20 models
Price and availability
What a machine costs decides as much as what fits inside it, so the price belongs on this page. What follows is only what the manufacturer publishes, with the market it applies to and the day it was read.
From $6,599 (United States), as published on 2026-10-01 (Source). Vendor declared
What we earn on this page
Nothing, today. There is no affiliate link on this page and no commercial agreement behind any figure on it. If a buying link ever appears here, it will be marked as such and the commission declared in this same block. Two rules do not change on that day: the ranking on this site is computed before commercial availability is applied, and «best» never means «pays most».