Home›Hardware›PC with Ryzen AI Max+ PRO 495 and 192 GB unified
PC with Ryzen AI Max+ PRO 495 and 192 GB unified
AMD chip with unified memory192 GiB273 GB/s15.4 TFLOPS
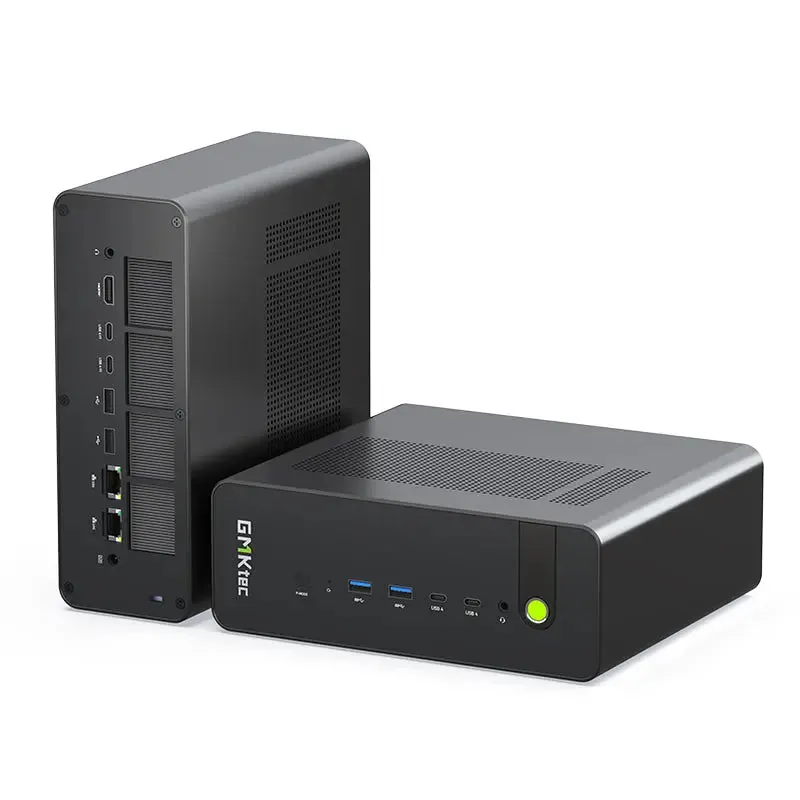
Once the system takes its share, this machine leaves 160.00 GiB for the model: room for 25 of the 28 models we measure at the reference compression, and the heaviest one that fits is deepseek-v4-flash. And how fast does it answer? That’s not down to the chip, but to its 273 GB/s of memory bandwidth.
Left for the model
Estimated
Memory bandwidth
Estimated
Models that fit
Measured by Local AI Scope
Videos: PC with Ryzen AI Max+ PRO 495 and 192 GB unified 2
The official videos we found most useful. Press play and it opens right here.
The videos live on YouTube, and nothing loads from there until you press play (no-cookie mode). The thumbnail is served by us.
The memory you can actually use
Unified memory is shared with the operating system and everything you have open. The reserve here is deliberately conservative; you can change it in the tool.
| Memory | GiB |
|---|---|
| Memory on the box | 192 |
| Reserved for the system | −3.00 |
| Beyond the limit the manufacturer sets for the GPU | −29.00 |
| Left for the model | 160.00 |
192 GB on the box, 160 for the model. AMD states that the Ryzen AI Max+ PRO 495 can dedicate up to 160 GB of its 192 GB to the graphics processor, and the graphics processor is what runs the model. So every figure on this page is computed with 160, not with the 189 that the box minus our system reserve would give. On Linux that limit is a driver setting that AMD documents as adjustable, but it publishes no maximum figure for it: we stick to the figure it does publish.
Memory bandwidth
Two different limits, and they are easy to mix up. While the model is writing its answer, bandwidth rules: every token means reading the weights it uses again — all of them in a dense model; in a mixture of experts, the shared layers plus only the active experts — so tokens per second is roughly bandwidth divided by that amount. While the model is reading your document, compute rules: the whole input is processed at once. That is why a laptop with no GPU can take minutes before the first word appears and then type at a tolerable pace.
273 GB/s — Derived, not published by the manufacturer · the manufacturer publishes the bus width but neither the memory speed nor the bandwidth. This figure is the usual arithmetic derivation () and we could not confirm it at source (Source).
Compute: 15.4 TFLOPS (estimate for this class of machine) — Estimated · the manufacturer does not publish this figure at all; ours is a conservative estimate, not a specification. The figures in this line do not all come from the same measure across machines, because each manufacturer publishes a different one. Compare them between machines only with that in mind.
Which models fit here, and which do not
Fitting means three things at once fit in the memory left over: the model file, its context memory, and the runtime’s working headroom. Context memory is computed from each model’s declared attention pattern layer by layer, not from the generic formula — which is why several models fit here that the generic formula would rule out.
| Model | Compression shown | Model size | 8k | 32k | 128k | Largest context that fits |
|---|---|---|---|---|---|---|
| qwen3-1.7b | Q4_K_M |
1.03 GiB | yes | yes | — | 32k |
| qwen3-4b-2507 | Q4_K_M |
2.33 GiB | yes | yes | yes | 256k |
| gemma4-e2b | Q4_K_M |
2.89 GiB | yes | yes | yes | 128k |
| gemma4-e4b | Q4_K_M |
4.63 GiB | yes | yes | yes | 128k |
| qwen3-8b | Q4_K_M |
4.68 GiB | yes | yes | — | 32k |
| granite-4.2-8b | Q4_K_M |
4.98 GiB | yes | yes | yes | 128k |
| qwen3.5-9b | Q4_K_M |
5.29 GiB | yes | yes | yes | 256k |
| gemma4-12b | Q4_K_M |
6.63 GiB | yes | yes | yes | 256k |
| phi-4 | Q4_K_M |
8.43 GiB | yes | — | — | 16k |
| gpt-oss-20b | Q4_K_M |
10.83 GiB | yes | yes | yes | 128k |
| mistral-small-24b | Q4_K_M |
13.35 GiB | yes | yes | yes | 128k |
| qwen3.8-27b | Q4_K_M |
15.33 GiB | yes | yes | yes | 256k |
| muse-glimmer-30b | Q4_K_M |
15.61 GiB | yes | yes | yes | 128k |
| qwen3.6-27b | Q4_K_M |
15.66 GiB | yes | yes | yes | 256k |
| gemma4-26b-a4b | Q4_K_M |
15.78 GiB | yes | yes | yes | 256k |
| gemma4-31b | Q4_K_M |
17.07 GiB | yes | yes | yes | 256k |
| qwen3-coder-30b | Q4_K_M |
17.28 GiB | yes | yes | yes | 256k |
| qwen3.6-35b-a3b | Q4_K_M |
20.61 GiB | yes | yes | yes | 256k |
| flint-40b | Q4_K_M |
23.61 GiB | yes | yes | yes | 256k |
| nemotron-3.5-lightning-30b | Q4_K_M |
23.73 GiB | yes | yes | yes | 256k |
| gpt-oss-120b | Q4_K_M |
58.46 GiB | yes | yes | yes | 128k |
| llama4-scout-17b | Q4_K_M |
60.87 GiB | yes | yes | yes | 1024k |
| nemotron-3.5-super-120b | Q4_K_M |
65.29 GiB | yes | yes | yes | 1024k |
| qwen3.8-flash-next | IQ4_XS |
87.25 GiB | yes | yes | yes | 256k |
| deepseek-v4-flash | IQ4_XS |
127.28 GiB | yes | yes | yes | 256k |
| glm-5.3-flash | Q4_K_M |
187.04 GiB | no | no | no | — |
| glm-5.2 | Q4_K_M |
433.83 GiB | no | no | no | — |
| mistral-large-4 | Q4_K_M |
591.21 GiB | no | no | no | — |
Sizes are the real published files at the reference compression, one step per row: Q4_K_M where the author publishes it, the nearest neighbour where they do not. Every row states which one it is showing. Q4_K_M is our quality floor: below it the loss is audible in the answers. A model that would only fit here at a harsher compression is listed as not fitting, on purpose. A dash in a context column means the model itself does not offer that context, so there is nothing to fit.
Models that fit — 25 of the 28 models measured
- qwen3-1.7b
Q4_K_M— context 32k tokens - qwen3-4b-2507
Q4_K_M— context 256k tokens - gemma4-e2b
Q4_K_M— context 128k tokens - gemma4-e4b
Q4_K_M— context 128k tokens - qwen3-8b
Q4_K_M— context 32k tokens - granite-4.2-8b
Q4_K_M— context 128k tokens - qwen3.5-9b
Q4_K_M— context 256k tokens - gemma4-12b
Q4_K_M— context 256k tokens - phi-4
Q4_K_M— context 16k tokens - gpt-oss-20b
Q4_K_M— context 128k tokens - mistral-small-24b
Q4_K_M— context 128k tokens - qwen3.8-27b
Q4_K_M— context 256k tokens - muse-glimmer-30b
Q4_K_M— context 128k tokens - qwen3.6-27b
Q4_K_M— context 256k tokens - gemma4-26b-a4b
Q4_K_M— context 256k tokens - gemma4-31b
Q4_K_M— context 256k tokens - qwen3-coder-30b
Q4_K_M— context 256k tokens - qwen3.6-35b-a3b
Q4_K_M— context 256k tokens - flint-40b
Q4_K_M— context 256k tokens - nemotron-3.5-lightning-30b
Q4_K_M— context 256k tokens - gpt-oss-120b
Q4_K_M— context 128k tokens - llama4-scout-17b
Q4_K_M— context 1024k tokens - nemotron-3.5-super-120b
Q4_K_M— context 1024k tokens - qwen3.8-flash-next
IQ4_XS— context 256k tokens - deepseek-v4-flash
IQ4_XS— context 256k tokens
Models that do not fit — 3 of the 28 models measured
- glm-5.3-flash
Q4_K_M— short by 27.80 GiB - glm-5.2
Q4_K_M— short by 275.12 GiB - mistral-large-4
Q4_K_M— short by 432.37 GiB
Willing to compress a bit more? Then not everything on this list is out of reach. In the 160.00 GiB of unified memory the manufacturer lets the GPU use, glm-5.3-flash runs at Q3_K_M (144.37 GiB) with up to 256k tokens of context. Below the compression in the table a model loses quality, and at Q3_K_M noticeably more; that is why our count sticks to the table.
The machines on either side
- Xiaomi AI Cube, 80 GB — engineering prototype — 77.00 GiB left for the model, 23 / 28 models
- PC with Ryzen AI Max+ 395 and 128 GB unified — 96.00 GiB left for the model, 24 / 28 models
- Mac Studio with M5 Max and 128 GB — 125.00 GiB left for the model, 24 / 28 models
- Mac Studio with M5 Ultra and 512 GB — 509.00 GiB left for the model, 27 / 28 models
Price and availability
What a machine costs decides as much as what fits inside it, so the price belongs on this page. What follows is only what the manufacturer publishes, with the market it applies to and the day it was read.
From $6,799 (United States), as published on 2026-10-09 (Source). Vendor declared
That is GMKtec’s EVO-X5 Pro with 192 GB and a 2 TB drive: the lowest price we found for this chip with 192 GB on a machine that is already shipping in the US (on 1 October it was $6,599). GMKtec’s European store sells the same configuration at €6,599, duty paid and shipped from its German warehouse; for orders placed from 16 October it expects to dispatch them between 20 and 30 November 2026. In its US store, on 30 October 2026 it showed the machine in stock with dispatch within 3 business days.
What we earn on this page
Nothing, today. There is no affiliate link on this page and no commercial agreement behind any figure on it. If a buying link ever appears here, it will be marked as such and the commission declared in this same block. Two rules do not change on that day: the ranking on this site is computed before commercial availability is applied, and «best» never means «pays most».